Artificial intelligence is becoming part of everyday operations across the life sciences industry. Pharmaceutical companies are exploring its potential to accelerate research, manage regulatory information, support medical affairs, and make better use of the enormous volumes of information generated throughout a product's lifecycle.
Yet as organizations invest in increasingly sophisticated AI systems, an important question often receives less attention: is the information these systems depend on actually ready to be used?
For global life sciences companies, the answer becomes particularly complicated when that information exists in multiple languages. A company may have years of translated regulatory documents, clinical trial materials, medical information responses, product labeling, and patient-facing content distributed across different platforms and markets. While these materials may have been translated accurately, that does not necessarily mean they are organized, connected, or structured in ways that allow AI systems to use them reliably.
Before organizations can become AI-ready, they need to consider whether their multilingual content is ready too.
The Difference Between Having Information and Being Able to Use It
Life sciences organizations rarely suffer from a shortage of information. The greater challenge is often finding, connecting, and maintaining the right information across departments, systems, and geographic regions.
Consider a pharmaceutical company that maintains product information in English, Spanish, Portuguese, German, and Japanese. Each version may be stored in a different repository, updated by different regional teams, and associated with different approval processes.
From a traditional document-management perspective, these materials may be perfectly usable. Employees know where to find them, and established procedures govern their updates.
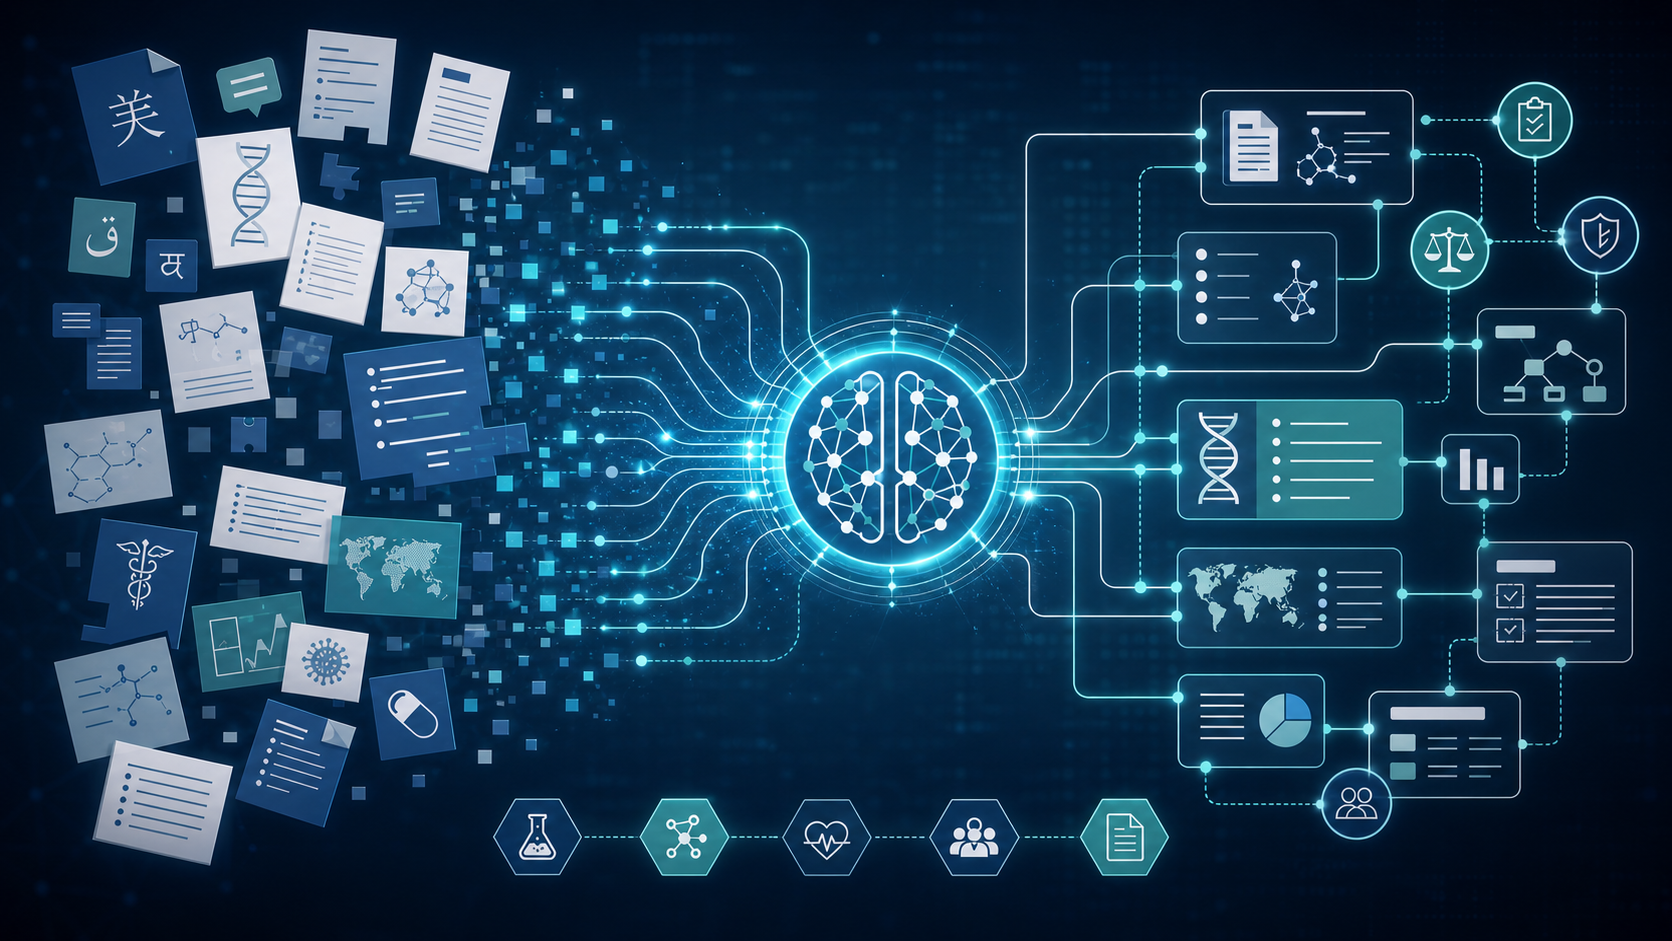
An AI-powered system, however, may need to identify relationships between those documents, determine which versions are current, recognize equivalent terminology, and retrieve information appropriate for a specific market.
If those relationships are not clearly documented, even a sophisticated system can struggle to distinguish between accurate, outdated, or contextually inappropriate information.
The problem is not necessarily translation quality. It is the infrastructure surrounding the translated content.
Why Multilingual Data Creates Additional Complexity
Language introduces several challenges that are easy to overlook when organizations design AI systems primarily around English-language information.
Medical terminology does not always follow a simple one-to-one relationship between languages. Different markets may use different accepted terms, regulatory conventions, product names, or classifications for related concepts. These differences may be entirely appropriate. A term used in European regulatory documentation, for example, may not be identical to the terminology expected in another jurisdiction.
The challenge arises when AI systems are expected to recognize these distinctions without access to the necessary linguistic and regulatory context.
Metadata is another important consideration. Information about a document's language, market, approval status, source version, and revision history helps determine whether that content is appropriate for a particular purpose.
Without consistent metadata, a system retrieving multilingual information may not reliably distinguish between a draft translation, an approved local version, or a document that has been superseded. In regulated environments, these distinctions are essential.
Terminology Management Becomes a Data Strategy
Terminology management has traditionally been associated with translation consistency. Glossaries, termbases, and style guides help linguists use approved terminology across projects and documents. In an AI-enabled environment, these resources can serve an additional purpose.
Well-maintained terminology assets can help organizations establish relationships between concepts, languages, products, and markets. When appropriately structured and integrated, they can support information retrieval, content classification, and more consistent multilingual processing. But simply having a glossary is not enough.
Organizations need to consider whether their terminology resources are current, whether they distinguish between regional variations, and whether they can be accessed and interpreted by the systems that need them. A terminology database developed exclusively for human reference may require additional structure before it can support automated workflows. This changes the conversation around linguistic assets.
Terminology is no longer valuable only because it improves translation consistency. It can also help determine how effectively organizations manage and reuse knowledge across languages.
What Happens When AI Retrieves the Wrong Version?
Imagine a medical information team using an AI-assisted search system to locate approved responses to healthcare professional inquiries. The organization maintains information across several languages and markets. A recent safety update has been incorporated into the English source material, but one regional version has not yet been updated.
If the system retrieves the outdated regional document without recognizing its status, it could generate or support a response based on superseded information. This example illustrates a broader issue.
AI systems do not automatically resolve inconsistencies in the information they access. Depending on their design, they may reproduce those inconsistencies, combine information from incompatible sources, or present outdated material in convincing language.
In life sciences, where content may be subject to regulatory approval and strict version controls, reliable AI use therefore depends on more than the model itself. It also depends on document governance, source traceability, access controls, and the ability to identify authoritative content across languages.
Building Multilingual Readiness Into AI Projects
For organizations planning AI initiatives, multilingual content should be considered during the earliest stages of implementation rather than treated as a localization requirement added later. This begins with understanding where information is stored, how different language versions are connected, and which systems maintain authoritative records. It also involves examining how terminology is managed, whether metadata is applied consistently, and how changes to source content are reflected across regional versions.
Language specialists can contribute valuable expertise to these discussions. Their understanding of terminology, linguistic variation, content relationships, and localization workflows can help organizations identify problems that might otherwise remain invisible during technology planning.
Importantly, not every AI application requires the same level of multilingual infrastructure. The requirements for an internal knowledge-search tool may differ significantly from those of a system supporting regulated medical information or patient-facing communication. The objective is to develop language-aware data practices that reflect the intended use and risk of each application.
AI Readiness Is Also Language Readiness
The life sciences industry's growing interest in AI is creating opportunities to rethink how information is organized, maintained, and shared. For global organizations, multilingual content is a substantial part of that information ecosystem.
Translations that were originally created to satisfy a specific regulatory requirement or support a regional launch may later become valuable resources for knowledge management, analytics, and AI-enabled workflows. But realizing that value requires more than accumulating translated documents. It requires understanding how information relates across languages, ensuring that authoritative versions can be identified, and maintaining the linguistic context necessary for accurate interpretation.
As life sciences organizations continue investing in AI, language should not be an afterthought in their data strategies. The question is no longer simply whether AI can work across languages. It is whether organizations have built the multilingual foundations that allow it to work reliably.